




What you receive in month one
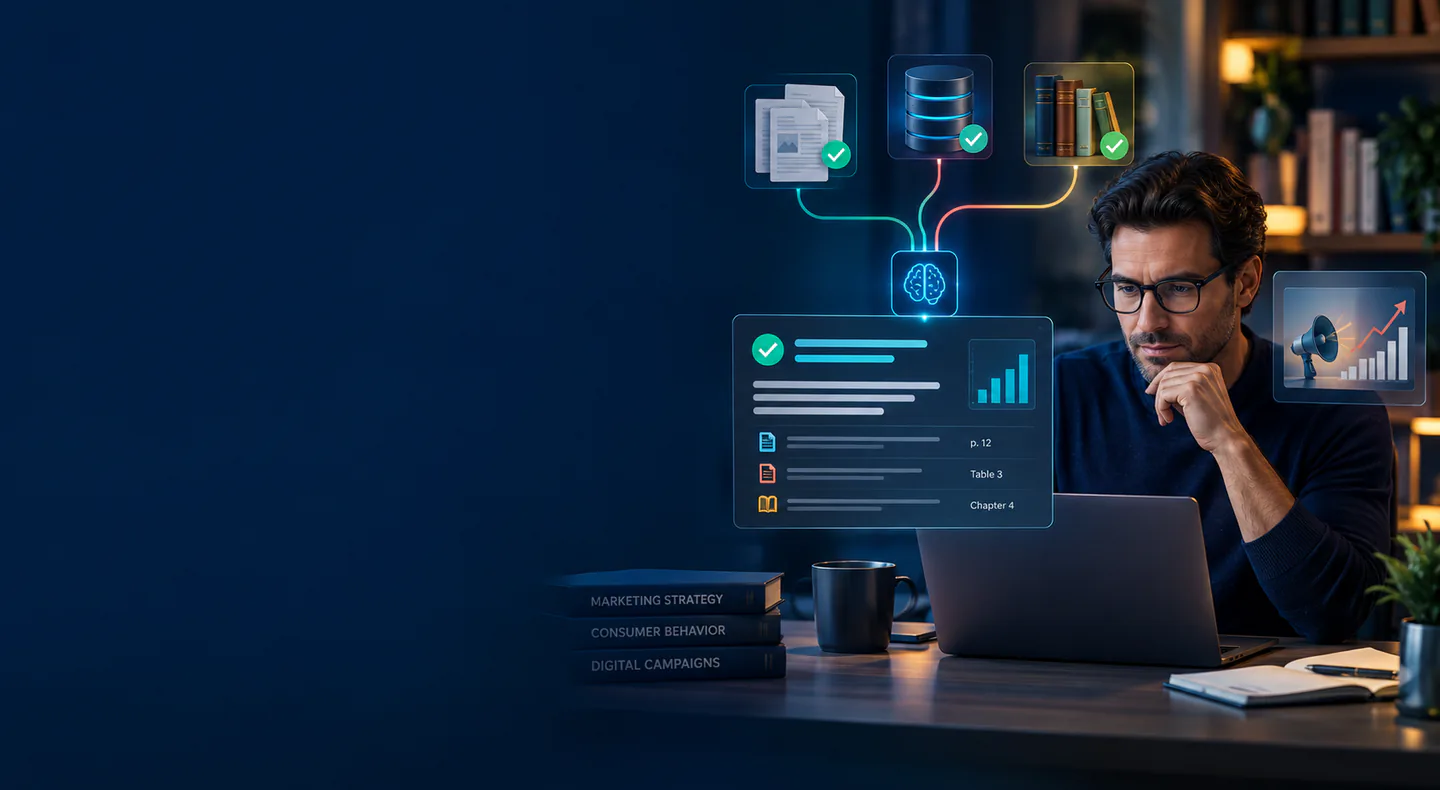
AI work is reported against an evaluation set built before any model is chosen. In the first month you receive the task definition with the inputs and acceptable outputs written down, the eval set of real cases with expected answers, and the scorecard showing accuracy, refusal behaviour and cost per run. The go/no-go checklist names what must hold before the pilot touches live traffic.
- 01Task definition: inputs, acceptable outputs, and the cases the system must decline
- 02Eval set: real cases with expected answers, reviewed by your team
- 03Scorecard: accuracy, refusal behaviour, latency and cost per run
- 04Go/no-go checklist: the thresholds the pilot must meet before launch
- 05Failure log: each wrong answer, its cause, and the fix applied